NVIDIA has released Auto Ontology, an open-source Python framework under the Apache-2.0 license that builds a semantic context layer from enterprise metadata, so AI agents write SQL against certified business definitions. According to MarkTechPost, which reported the release on 2 November 2026, NVIDIA says the tool cut ontology build time by 90% in its own testing.
The problem it targets is simple. As the repository puts it, a fast revenue answer is worthless if the number is wrong. NVIDIA Auto Ontology tries to stop agents from guessing which table holds a metric and what a field actually means.
What does Auto Ontology do for an agent?
It sits between an agent and the data warehouse. According to the source, it tells the agent where data lives, what fields mean, whether a field should be used, how to use it, and where it came from. The project describes five stages:
- Discover: generate ontologies from metadata and connect existing semantic models.
- Ground: give agents trusted meaning for metrics, entities and relationships.
- Validate: check generated queries against certified definitions and lineage.
- Expose: serve context through MCP, a CLI and an API.
- Learn: fold certified corrections back into the ontology.
NVIDIA's developer page frames the output as a starting ontology. Business experts still have to test, refine and certify it before agents can rely on it.
How is the system built?
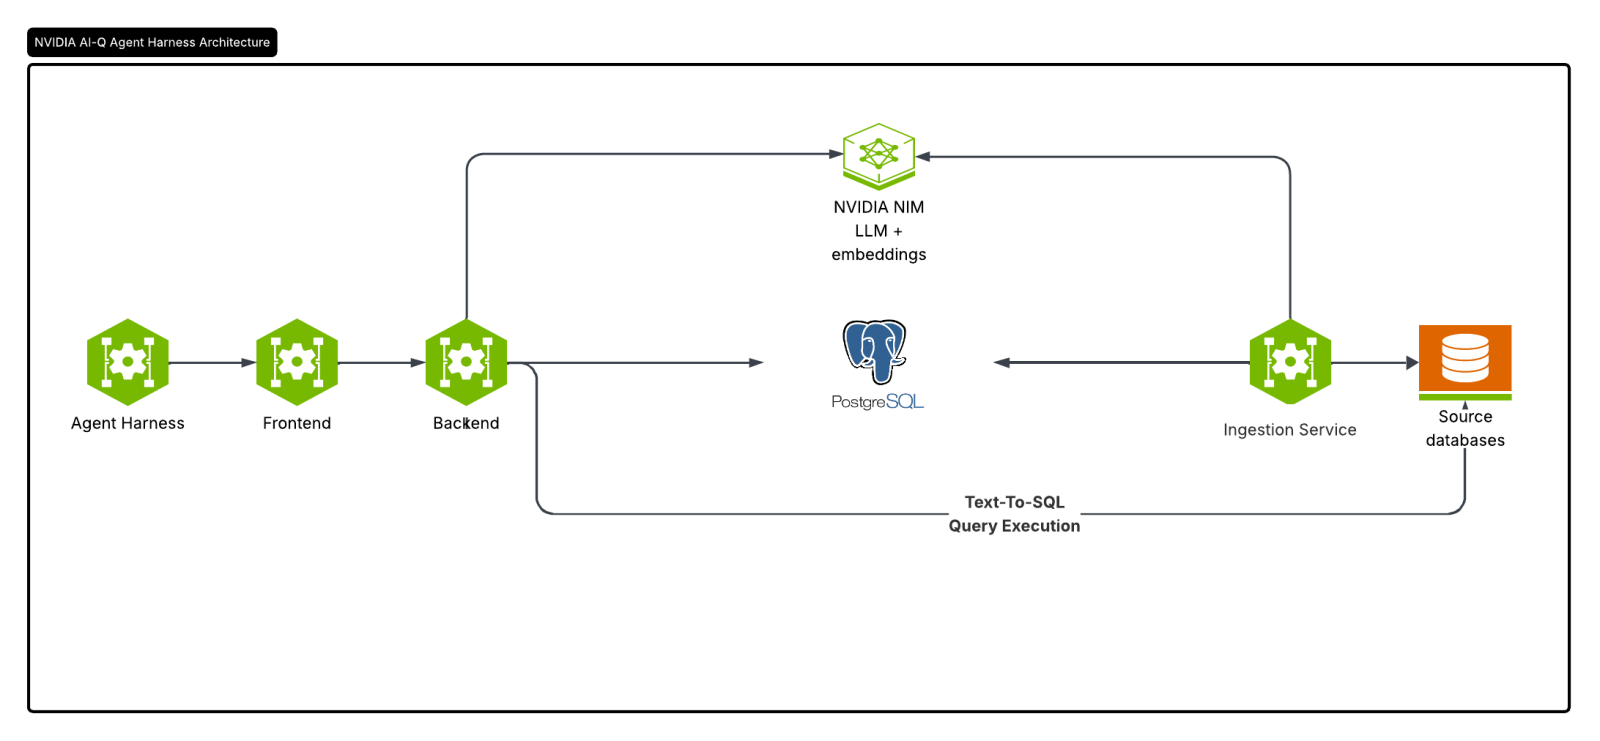
The stack has four core services. A Next.js 16 frontend handles the web UI and authentication on port 3000. A FastAPI backend with LangChain runs chat, NL-to-SQL and catalog APIs on port 3001. An ingestion worker writes embeddings on port 3002. Postgres with pgvector stores the catalog, the ontology and the vectors.
Source databases can be Databricks, Postgres, Snowflake or DuckDB. Models are configured through environment 'triplets' of endpoint, key and model, with separate roles for reasoning, non-reasoning, embedding and reranking. Any OpenAI-compatible endpoint works. The defaults are NVIDIA models: nvidia/nemotron-3-nano-30b-a3b as the default LLM, with Nemotron embedding and reranking models.
What can an agent call through MCP?
The MCP server documentation describes nine read-only tools. The central one is ask_question, which returns the answer, the SQL and the rows as separate fields. Results are capped at 100 rows. check_readiness confirms that a compiled semantic layer and a live database connection exist.
There is no tool for browsing raw schemas. NVIDIA chose that on purpose, so agents reach data only through the semantic layer. The underlying OpenAPI specification publishes 87 operations. Sign-in runs through OAuth, and according to the source, every call carries the signed-in user's permissions.
Does the text-to-SQL accuracy hold up?
The source does not provide any. It reports zero published text-to-SQL accuracy scores. NVIDIA ships a separate harness, auto-ontology-eval, which runs two arms in NeMo Gym: a schema-only LLM control and the ontology-grounded agent. Scoring uses deterministic execution match, with no LLM judge, so the same query returning the same rows gets the same score.
The bundled datasets are BIRD Dev (1,534 questions across 11 databases), Mini-Dev (500 questions), FDABench-Lite (169 questions) and BEAVER, which defaults to a 100-question sample. The harness repository itself names two limitations. Optional few-shot exemplars and value anchors go to the ontology arm only, so a measured gain that uses them reflects those inputs, not grounding alone. The tested configuration also routes both arms through a Claude model on NVIDIA's inference gateway, so results may not carry over to other models.
How do you get started?
For a local stack, fill in the .env file and run docker compose up -d --build. Kubernetes users get a Helm chart and a DEPLOYMENT.md guide. NVIDIA also publishes the backend as an NGC container. An NVIDIA API key from build.nvidia.com covers the default models. Inference can use hosted NVIDIA NIM endpoints or self-hosted NIMs.
Who it is for and where it falls short
The project suits teams that already run a supported warehouse, have business owners who can certify metric definitions, and want agents to answer metric questions through MCP. It is a poor fit for teams that expect accurate answers without that review step.
- Requirements: a supported source database, a model endpoint, and either Docker or Kubernetes. The default models need an NVIDIA API key.
- Evidence gaps: the source publishes no text-to-SQL accuracy scores, and the 90% build-time figure is NVIDIA's own self-reported result.
- Maturity: the source does not state a version number or a maintenance schedule. GitHub data as of 2 November 2026 shows 708 stars and 89 forks, with the last commit pushed on 2 November 2026.
- Alternatives: the source does not compare Auto Ontology with other semantic layers, and its comparison section is empty.
Bottom line: Auto Ontology is worth a pilot if you run one of the supported databases and have people who can certify metric definitions. Run the eval harness on your own data before you trust agent answers in production.
Source and verification: This article is based on a MarkTechPost report published 2 November 2026 about NVIDIA's release. Repository figures (708 stars, 89 forks, Apache-2.0 license, Python as the main language, last commit 2 November 2026) come from the GitHub API as of 2 November 2026. The 90% build-time figure is NVIDIA's self-reported claim and has not been independently verified.
Related: datasette-llm 0.1a9 Now Uses LLM's Default Model · DeepSeek Open-Sources dsh-superagent, an MIT-Licensed Coding Agent
Comments (0)